We present Kandinsky S2V 1.0, an open family of speech-to-video models for con-
trollable audio-driven human animation, comprising Kandinsky S2V 1.0 Lite (2B parameters)
and Kandinsky S2V 1.0 Pro (21B parameters). From a single reference image, a speech wave-
form, and a text prompt, the models generate long-form 25 FPS video in which lip motion,
expression, pose, and gesture follow the speech. The architecture draws text and audio
conditioning from one Qwen2.5-Omni model and adds a reference-aware three-scale vi-
sual memory. Training starts from the Kandinsky 5.0 Video foundation models [1] and com-
bines mixed reference-memory layouts with an area-adaptive face loss. The training corpus
contains 1.17M single-speaker clips selected by active-speaker detection, with captions gen-
erated directly in English and Russian. A side-by-side human evaluation against the strongest
open-source baseline and two proprietary commercial models shows that Kandinsky S2V 1.0
Pro performs comparably to or better than these models on average and is also preferred
for lip synchronization. On common speech to video benchmarks, Pro ranks among the top
performing models according to mean rank and min-max score over five reported metrics.
Beyond the base models, we provide π-Flow distilled variants of both Lite and Pro. The dis-
tilled Kandinsky S2V 1.0 Pro model generates video in 16 sampling steps without classifier-free
guidance, achieving a 5.4× end-to-end speedup over the base model, while matching or
exceeding it on nearly all reported benchmark metrics. To accelerate open research and
deployment in speech-to-video generation, we release the code, model checkpoints, and
diffusers integration under the MIT license.
Method
Method Overview
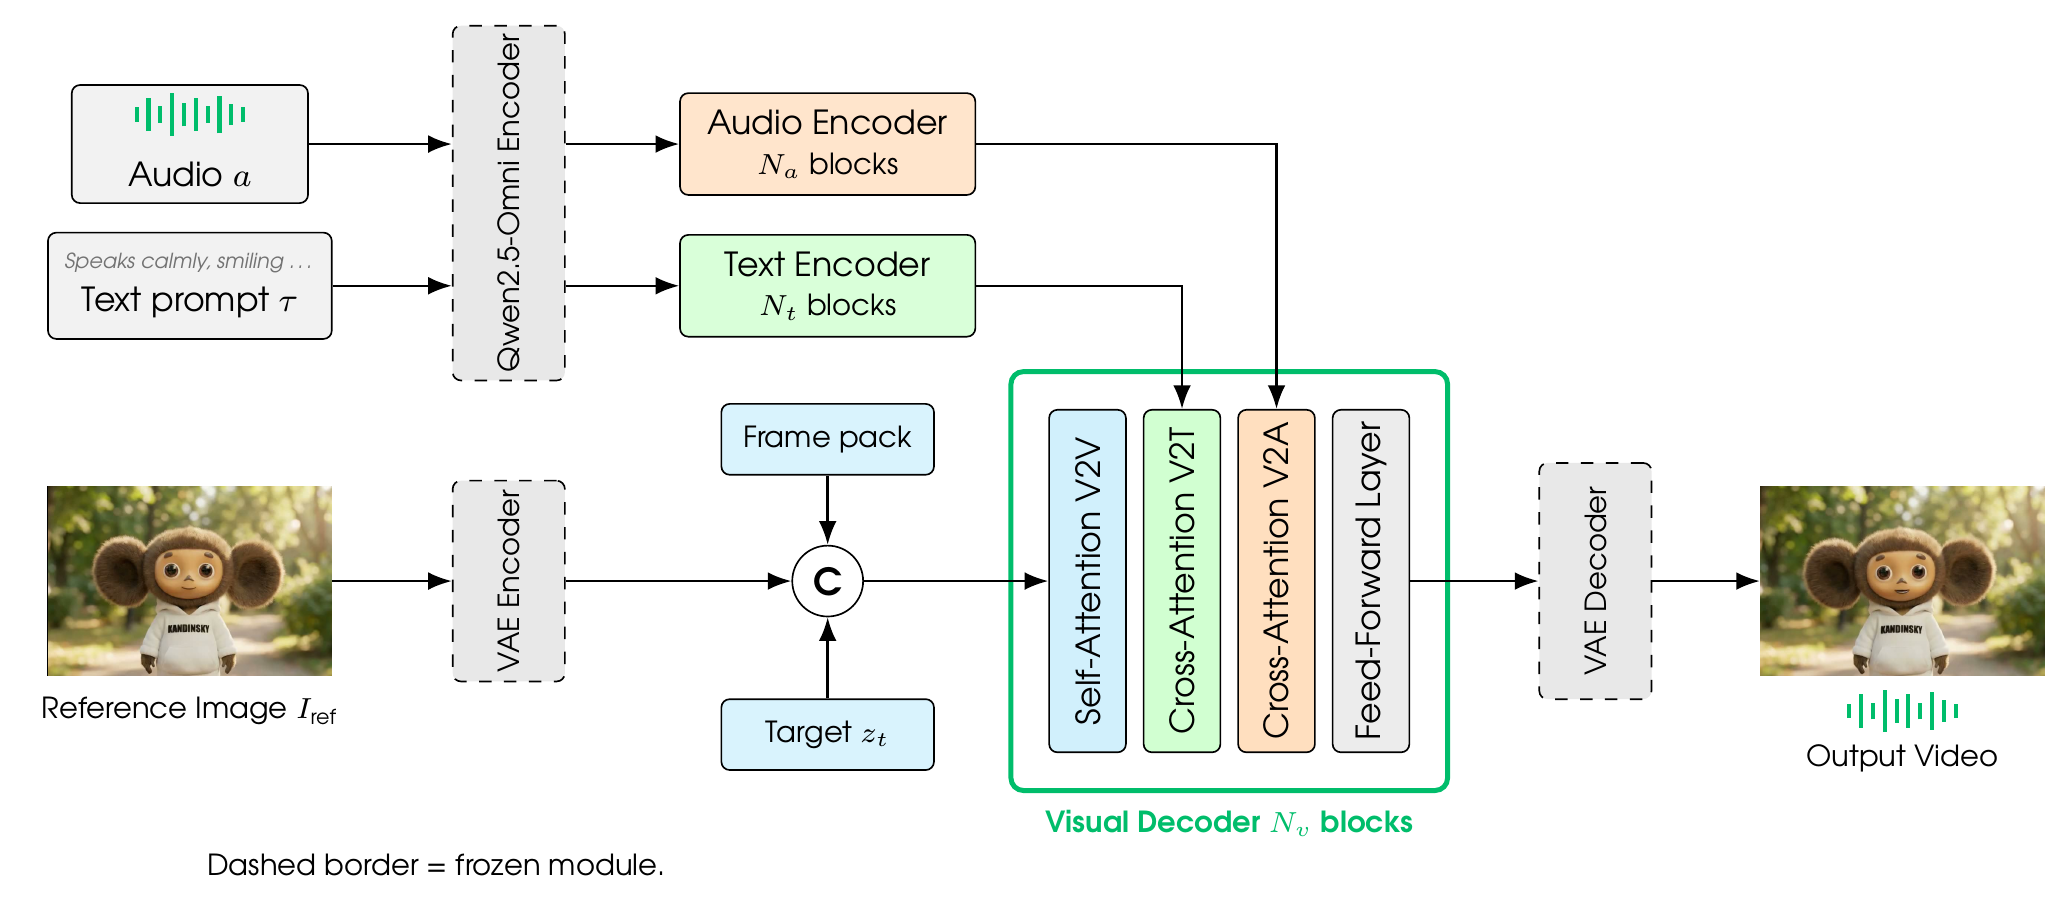
Kandinsky S2V 1.0 is a 3D Diffusion Transformer trained with a flow-matching objective
in the latent space of a frozen Hunyuan video VAE, and initialized from the Kandinsky
5.0 Video text-to-video checkpoints. Three design choices carry the results above:
(1) a shared Qwen2.5-Omni front end, whose frozen
Thinker and audio tower feed two trainable DiT-internal stacks, replacing the
standalone Wav2Vec or Whisper path used by most recent S2V systems;
(2) a reference-aware three-scale FramePack memory with mixed reference
placement, which packs past frames at progressively coarser patch sizes and
keeps the identity reference far from the target on the temporal RoPE axis,
suppressing pose copying and autoregressive looping in long rollouts; and
(3) an area-adaptive face loss, weighted inversely to the face-area
ratio of the clip so lip-sync supervision survives when the speaker occupies a small
part of the frame. Audio enters only at periodically spaced decoder blocks — 13
of 32 in the 2B model and 18 of 60 in the 21B Pro model — aligned per latent
frame. Both models are trained at standard definition with dense attention, and the
same checkpoints generate high-definition video without a dedicated training stage.
Text features from the frozen Qwen2.5-Omni Thinker and acoustic features from its
frozen audio tower feed two trainable DiT-internal stacks. The reference image is
encoded by a frozen Hunyuan 3D VAE and concatenated (C) with the noisy target latent and the
multi-scale FramePack memory of past frames. Each DiT block applies self-attention
(V2V), cross-attention to text (V2T), an optional cross-attention to audio (V2A),
and a feed-forward layer.